GPU server A
- 96GB
- 96GB
- 96GB
- 96GB
- Expansion
- Expansion
- Expansion
- Expansion
4 GPUs initially · 8-GPU-capable chassis
- 96+ physical CPU cores
- 1TB ECC memory
- 15–20TB local NVMe
- Mirrored boot SSDs
Daffodil · AI Infrastructure
Building the foundation for Bangladesh’s AI future.
Daffodil is developing a shared AI foundation for Bangladesh, bringing together GPU computing, private knowledge services, research environments and governed automation. Daffodil’s own universities and businesses are the pilot ground, so what proves useful can be offered more widely across Bangladesh as the platform matures.
Infrastructure programme in development · Architecture showcase
Why Daffodil
Daffodil brings together education, research, technology development, connectivity and data-center operations. The planned AI platform connects these strengths through shared resources and accountable access, so each institution and business can build useful services without creating a separate AI stack for every team.
Data-center and connectivity experience.
Useful AI for learning, research and everyday work.
Internal validation, followed by selected external services.
Architecture
The proposed architecture connects a resilient technical foundation to approved models, institutional knowledge and applications. Security, governance and recovery span the whole system.
Infrastructure OS means the shared management and orchestration layer. Existing business applications retain their owners and responsibilities. DOL Unified remains the internal operations system, connected through approved APIs and events.
Reference infrastructure
Planned reference configuration · Final OEM design and acceptance pending
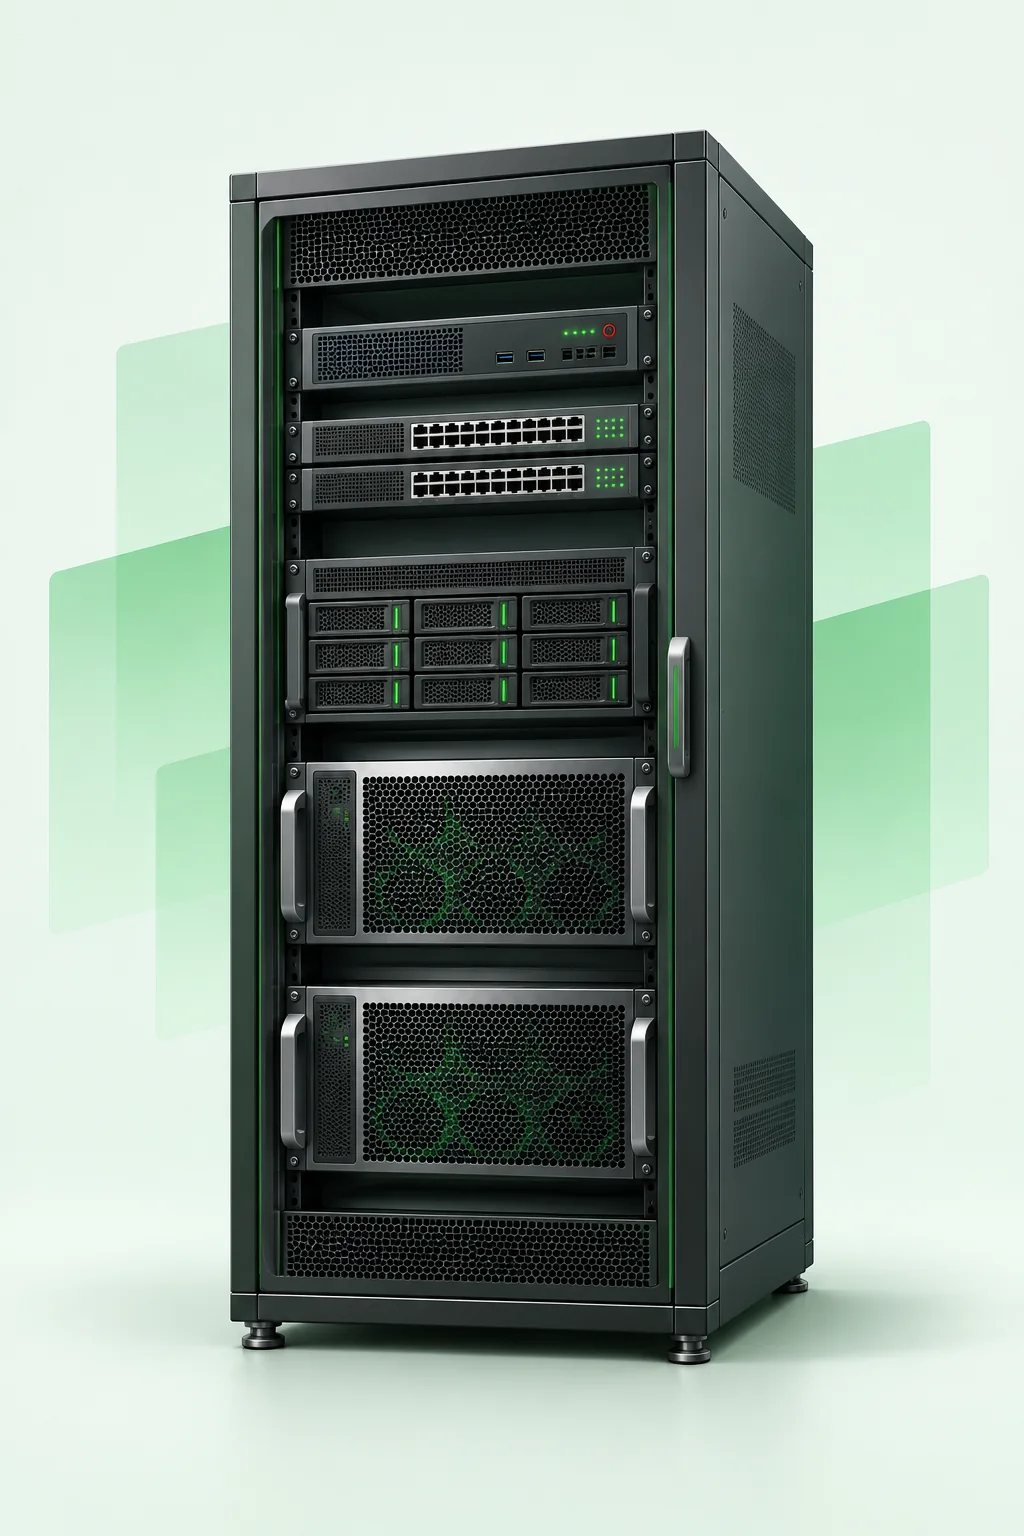
Planned AI compute at Daffodil Smart City, Ashulia, with a protected off-site recovery copy at Dhanmondi.
4 GPUs initially · 8-GPU-capable chassis
4 GPUs initially · 8-GPU-capable chassis
| Building block | Planned specification |
|---|---|
| Production compute | 2 independent GPU servers, with 4 NVIDIA RTX PRO 6000 Blackwell Server Edition 96GB GPUs per server at the initial stage: 8 GPUs total. |
| Expansion pathway | Each server is designed around an 8-GPU-capable chassis, allowing a proposed expansion to 16 matching GPUs total, subject to supported configuration and facility acceptance. |
| Server resources | Reference requirement per GPU server: at least 96 physical CPU cores, 1TB ECC memory, 15–20TB enterprise local NVMe and mirrored boot SSDs. |
| Shared storage | 1 logical HA storage system, with at least 100TB protected usable capacity, expandable to at least 300TB. |
| Network fabric | Redundant 100GbE AI and storage networking, with dual-connected servers and separate management access. |
| Central management | 1 logical HA management platform, implemented using 3 small nodes or a validated HA equivalent. |
| Backup and recovery | A separate dedicated backup system, protected copies and tested restoration, with a planned off-site recovery copy. |
Eight 96GB GPUs give 768GB of GPU memory in total, distributed across individual GPUs and servers. It is not one pooled accelerator.
These are design requirements, not installed capacity or a final vendor bill of materials. Recovery copies support restoration; they do not imply a second live GPU site.
Two AI Labs with 52 user endpoints: 25 student stations and one instructor station per lab. The reference is two shared H200 NVL-class GPUs or a validated equivalent. The vendor must propose the server count, memory, local NVMe, mirrored boot drives and protected user storage. The lab GPUs are separate from the central production GPU capacity.
See the AI Labs pathwayAcross Daffodil
Illustrative use cases for phased assessment and approval
Supervised AI exercises, coding assistance and project environments in the planned AI Labs, with quotas, isolation and a reviewed path for promising projects.
Reproducible experiments, permitted datasets, selected model adaptation and compute reservations.
Policy search, document drafting and service-request assistance, with access limited to the user’s responsibilities.
Document assistance, analysis preparation and management summaries. Financial approvals and consequential decisions remain with authorized people.
Knowledge support, service-desk drafting and AI-assisted operational analysis linked to approved workflows.
Business-specific knowledge assistants, technical support preparation and approved application integrations.
Supervised research, analysis of approved evidence and human-reviewed findings in isolated environments.
These examples describe intended opportunities. Each use case needs an accountable owner, permitted data, evaluation and an approved deployment path. Existing systems and teams keep their decision authority.
Planned AI Labs
Planned academic infrastructure · Final lab sizing and acceptance pending
Two planned AI Labs give students and faculty hands-on AI computing for courses, research and projects. Both labs share a dedicated academic GPU pool, kept separate from the central production platform, and the most promising projects have a reviewed path into real use across Daffodil.
Both labs share two H200 NVL-class GPUs, or a validated equivalent. Lab PCs stay standard: GPU time is allocated through accounts and quotas, not one GPU per seat.
Courses, notebooks, AI agents, computer vision, model fine-tuning within quota and project work, guided by faculty.
The lab GPUs and the lab network zone are separate from production. Each user has an account, a quota and a resettable environment, so lab work is designed not to compete with institutional services.
A promising project can grow into a Daffodil application or institutional service, and in future a solution for partners, but only through review, approval and an isolated pilot.
Synthetic example · Illustrative project
A Bangla course-notes assistant built by a final-year student team
No student project receives unrestricted production access. Every promotion is owned, mentored, isolated and auditable.
The lab design is a planned baseline: final sizing follows a representative 52-seat commissioning test, and the vendor proposes the lab server configuration. The lab GPUs are separate from the eight production GPUs.
Follow one request
Synthetic example · No live system
“Which policy applies to this staff training request?”
The model cannot grant itself access. Permission checks also apply when an answer is delivered or an action is executed.
Knowledge, models and research
Retrieval-augmented generation, or RAG, finds permitted institutional material when answering a question. It does not mean training a model on every Daffodil document.
Inference runs a selected, registered model for an approved task, with routing and resource controls.
Research teams can evaluate permitted datasets and selected fine-tuning methods within supported capacity, isolated environments and review gates.
The programme focuses on useful, evaluated AI and governed agents. It does not claim artificial general intelligence or a completed Daffodil frontier model.
Governance and cybersecurity
Design controls
The planned platform uses a local-first, governed hybrid approach. Sensitive workloads are intended for approved local processing. Any use of an external model requires an allowed data classification, approved provider terms and an authorized route. A timeout does not authorize sending private data elsewhere.
Access, model, routing and usage metadata support accountability. Full prompts or document content should be retained only for a defined, approved purpose with appropriate access and retention controls.
AI can assist with analysis and recommendations. Sensitive data onboarding, production model releases, high-impact actions and recovery decisions remain subject to responsible human approval.
Student and cybersecurity research use approved datasets, isolated environments and supervised evaluation. Research access does not grant production privileges; a selected student project reaches real use only through academic, technical and programme approval and an isolated pilot.
Delivery pathway
Validate the platform, security controls, backup recovery and operational ownership.
Start with an institutional knowledge assistant, service-desk drafting and a supervised academic cohort.
Review answer quality, adoption, time saved, service reliability and cost per useful outcome.
Confirm spare non-reserve capacity, tenant isolation, data terms, support and commercial readiness.
These are readiness stages, not completed milestones or promised launch dates.
Bangladesh service pathway
Daffodil’s institutions are where the platform is tested with real users and real workloads. What proves useful is then intended to reach organizations across Bangladesh, starting with selected enterprise pilots. The first candidate services are private company knowledge assistants and employee productivity support. Later opportunities may include managed model APIs, supported GPU workloads, research services and GPU colocation, subject to capacity, facility readiness and service agreements.
Company knowledge assistants and employee productivity support. The first candidate.
Approved models served through managed APIs.
Supported research, training and inference workloads.
Space, power and connectivity for customer GPU systems, where facilities allow.
Daffodil Smart City, Ashulia
Piloted at Daffodil. Built for Bangladesh.
Future pathway · subject to readiness
District boundaries: geoBoundaries, BBS & OCHA (CC BY 3.0 IGO)Talk to us
We welcome conversations with institutions, businesses and research partners about future use cases. This is an expression-of-interest pathway; availability, specifications and commercial terms will follow readiness assessment.
Infrastructure programme in development · Architecture showcase